Advertisement

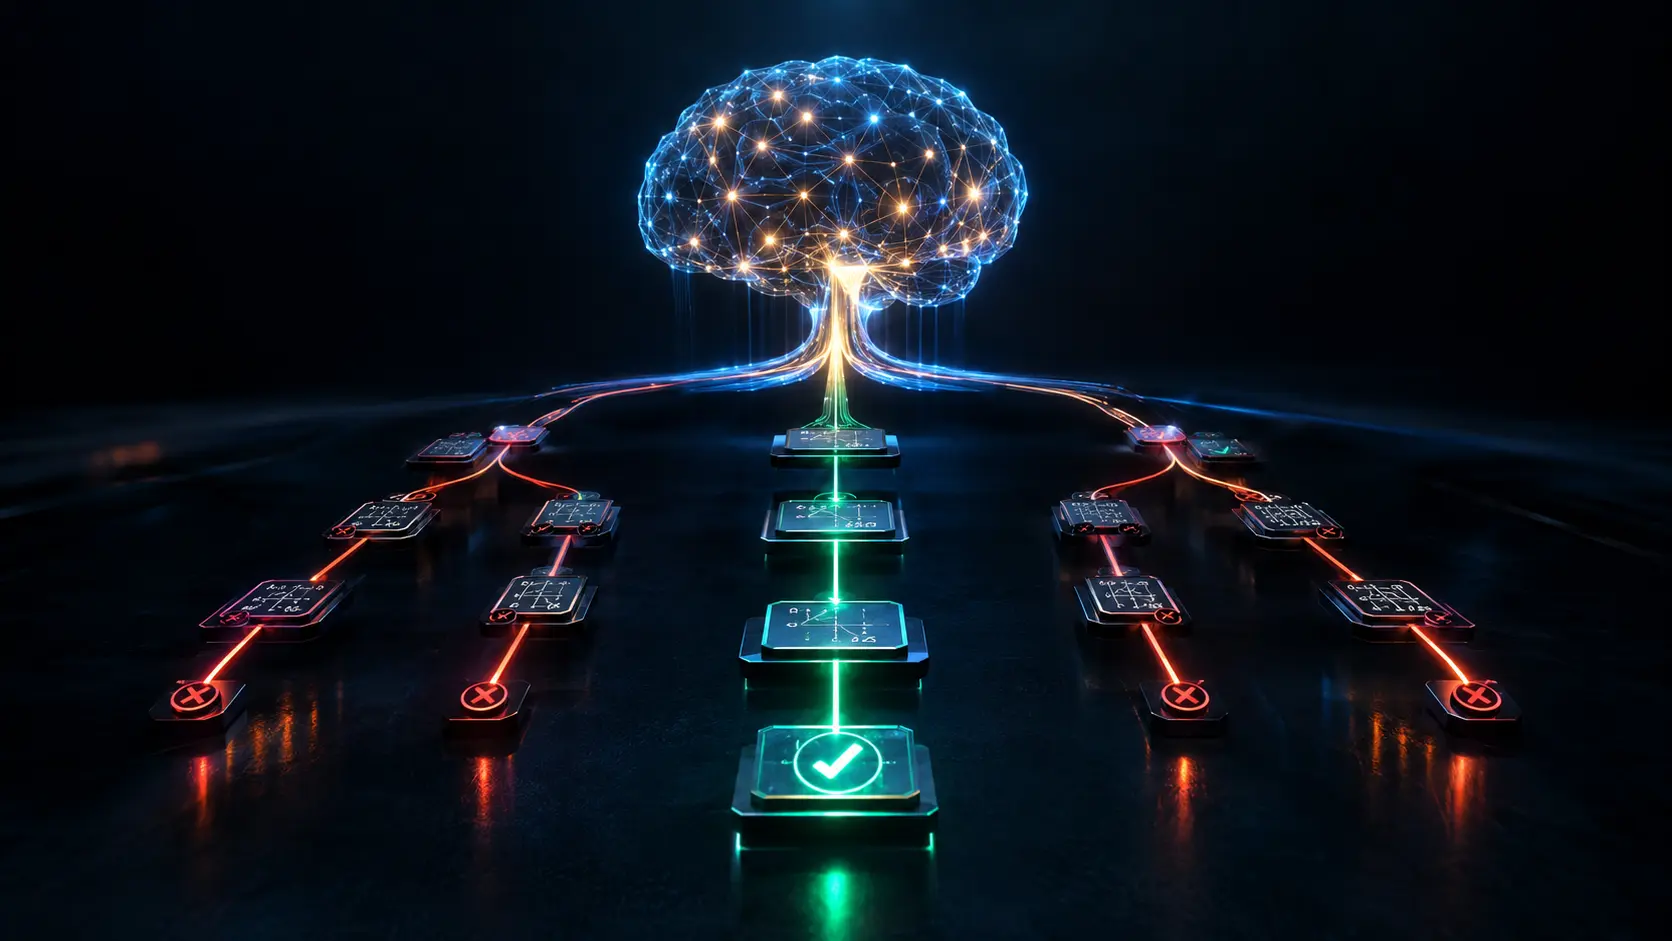

For the past five years, the artificial intelligence industry relied on a brute-force economic strategy: to make a model smarter, you had to build a bigger supercomputer and feed it more data. This “pre-training scaling law” created a monopoly where only a few trillion-dollar companies could afford to build frontier AI. But a monumental mathematical pivot has just shattered this monopoly. We are no longer just making models bigger; we are forcing them to think longer.
Why should you care right now? Because a new architecture called Test-Time Compute Scaling allows a cheap, open-source model running on standard hardware to definitively outperform massive, trillion-parameter leviathans on complex logic, coding, and math. By utilizing search algorithms and step-by-step verifiers, engineers have taught AI to pause, explore multiple logical paths, and mathematically check its own work before speaking. The era of the “instant guess” is officially over. We have entered the era of machine reasoning, and it is actively shifting billions of dollars in cloud computing infrastructure from the training phase directly to the inference phase.
What is Test-Time Compute Scaling?
Test-Time Compute Scaling is an artificial intelligence framework that improves a model’s logical reasoning by dedicating more processing power during generation (inference) rather than during initial training. It utilizes search algorithms and step-by-step verifiers to explore, evaluate, and correct multiple reasoning paths before producing a final answer.
At a Glance
- The Physics Problem: Standard AI writes word-by-word without looking ahead. If it makes a mistake on step 2 of a 10-step math problem, it cannot backtrack, guaranteeing a failure.
- The Reasoning Solution: Give the AI a “scratchpad.” Allow it to generate five different ways to solve step 2, evaluate which one is best, and discard the rest before moving to step 3.
- The Mechanism: This is driven by Monte Carlo Tree Search (MCTS) to explore paths, and Process Reward Models (PRMs) to mathematically score the quality of each individual step.
- The Strategic Value: It democratizes high-level AI. A smaller, cheaper model that is allowed to “think” for 30 seconds can solve problems that a massive, expensive model fails to solve in 1 second.
In Simple Words
Imagine asking two people to solve a complex algebra equation.
A Standard LLM is like a student who looks at the equation and instantly blurts out the first answer that comes to their head. It is incredibly fast, and if the question is simple, it is usually right. But if the question requires deep logic, guessing the whole answer instantly almost always results in a mistake.
A Test-Time Compute Model is like a mathematician with a whiteboard. It pauses. It writes out three different formulas. It tests the first one, realizes it leads to a dead end, erases it, and tries the second one. It checks its own math at every single step. After 30 seconds of internal drafting and erasing, it turns around and gives you the perfect, verified answer.
We have finally given artificial intelligence a whiteboard.
Why This Matters
For AI Researchers, MLOps Engineers, and Cloud Architects, this solves the Pre-Training Data Wall.
The AI industry is rapidly running out of high-quality human text to train on. Furthermore, training a massive foundation model now costs upwards of a billion dollars in electricity and GPUs.
Test-Time Compute offers a completely different axis of scaling. Instead of spending a billion dollars upfront to train a model to memorize answers, you train a smaller model to understand the rules of logic, and you spend your compute budget during the actual user query. For Cloud Architects, this means the infrastructure bottleneck is shifting: data centers are optimizing less for massive, synchronized training clusters, and more for high-throughput, dynamic inference clusters.
Micro-Insight: The defining metric of AI capability is shifting from “Parameter Count” to “Thinking Tokens.” The longer you allow the model to compute in real-time, the higher its functional IQ becomes.
The Shift to System 2 AI Reasoning
We are witnessing the System 1 to System 2 AI Transition.
In human psychology, System 1 is fast, instinctive, and automatic (recognizing a face). System 2 is slow, deliberate, and logical (multiplying 14 by 27). For a decade, deep learning was trapped in System 1. Models generated text entirely on statistical instinct. The integration of search trees and verifiers marks the first true manifestation of the AI reasoning paradigm and System 2 machine intelligence—a system capable of deliberate planning, self-correction, and navigating complex, multi-step logical constraints.
How Test-Time Compute Scaling Works (MCTS & PRMs)
To make an AI pause, think, and backtrack, you must completely overhaul the generation pipeline. Here is the first-principles breakdown of the architecture.
1. The Fundamental Problem: The Autoregressive Trap
Standard LLMs generate text autoregressively—predicting the next token based purely on the previous tokens. They are mathematically incapable of planning ahead. If an AI writes a flawed line of code in the first paragraph, it is trapped. Because it can only move forward, it will hallucinate the rest of the program to justify its earlier mistake.
2. The Core Mechanism: Monte Carlo Tree Search (MCTS)
To escape this trap, engineers borrow a concept from AlphaGo: Monte Carlo Tree Search.
Instead of outputting one sequence of tokens, the AI generates a “tree” of possibilities. Given a prompt, it generates three different opening logical steps (Branch A, B, and C). From Branch A, it generates three more sub-steps. The model explores these branches, simulating the future outcome of the logic. If a branch looks like a dead end, it stops computing that path (pruning) and redirects its compute power to the more promising branches.
3. Technical Depth: ORMs vs. PRMs
How does the AI know if a branch is promising? It uses a Reward Model.
- Outcome Reward Models (ORM): Look at the final answer and grade it Pass/Fail. This is inefficient because it requires generating the entire answer before knowing if it’s wrong.
- Process Reward Models (PRM): A secondary neural network trained specifically to grade individual steps of reasoning. As the main model builds its MCTS tree, the PRM acts as a strict teacher, scoring every single sentence. If the PRM gives step 2 a low score, the MCTS algorithm instantly abandons the branch and backtracks.
Plain-English Takeaway: The generator creates the ideas, the PRM grades the ideas in real-time, and the MCTS acts as the manager, constantly steering the AI away from bad logic and toward the correct solution.
4. Technical Depth: Dynamic Token Budgets
In standard AI, the user prompt dictates the compute cost. In Test-Time Compute, the complexity of the problem dictates the cost.
The system utilizes a “Token Budget.” The user might authorize the model to use up to 10,000 “thinking tokens” before returning an answer. The model uses these invisible tokens to generate its internal scratchpad, debate itself, and run PRM verifications. The harder the problem, the more thinking tokens it burns before presenting the final, clean answer to the user.
5. Real-World Consequences: Hallucination Suppression
Because the PRM actively punishes illogical jumps, the model is mathematically forced to ground its answers. If it tries to invent a fake legal precedent, the PRM scores the step as invalid, the branch is pruned, and the hallucination never reaches the user. This architecture functionally eradicates confident hallucinations in structured domains like math and code.
Reasoning vs. Compute Tradeoff Simulator
System 1 Autoregressive Generation vs. System 2 Test-Time Compute (MCTS & PRMs)
Problem Complexity
Level 5
Model Architecture
Standard (Instant)
Test-Time (MCTS+PRM)
Thinking Tokens Burned
0
Logical Accuracy
0%
Verification Status
IDLE
Internal Logic Tree (Reasoning Traces)
AWAITING PROMPT
Compute Expended vs. Target Accuracy
Real-World Applications
Test-time compute scaling is already redefining the benchmarks of frontier AI models.
OpenAI’s o1 (Strawberry): OpenAI introduced the OpenAI o1 architecture, completely built around test-time compute and reinforcement learning. When given the American Invitational Mathematics Examination (AIME), a standard GPT-4 model scores roughly 12%. By utilizing internal chain-of-thought reasoning and verifiers, the o1 model achieved an 83% accuracy, operating at the level of the top 500 high school math students in the United States. The model literally “thinks” for up to a minute, exploring logical branches before outputting text.
Autonomous Software Engineering (SWE-bench): Coding requires rigorous planning. If an AI alters a database schema in step 1, it must remember to update the API endpoints in step 4. Standard models fail this cascade of logic. By applying MCTS to codebase integration, AI coding agents can generate a patch, run a simulated compiler test (using a deterministic reward model), observe the syntax error, backtrack, and rewrite the patch autonomously until the code compiles perfectly.
Mathematical Theorem Proving: Companies like DeepMind have utilized specialized search trees to solve previously unsolved geometry problems (e.g., AlphaGeometry). By combining a language model (to generate creative mathematical steps) with a symbolic engine (to rigorously verify those steps), the AI searches through millions of potential logical proofs, verifying each step, until it discovers a novel, mathematically sound theorem.
Economic & Strategic Impact
The core strategic consequence of Test-Time Compute is The Inference Compute Boom.
For years, NVIDIA’s massive revenue growth was driven by hyperscalers buying GPUs to train models. Inference (simply running the model) was cheap and fast.
Test-Time Compute flips this dynamic. If an AI spends 45 seconds exploring a search tree to answer a complex coding prompt, it is burning exponentially more inference compute than a standard model. This is driving a massive strategic pivot in hardware design and data center architecture. We are moving from a world where we spend $100 million to train a model that costs $0.01 per query, to a world where we train smaller, cheaper models but happily pay $2.00 per query because the model is performing high-value, verified cognitive labor.
Advantages of Test-Time Compute in AI
- Human-Level Logic: Surpasses traditional LLMs in math, coding, and multi-step reasoning by allowing the model to self-correct before speaking.
- Cost-Efficient Scaling: Allows developers to deploy smaller, cheaper models (e.g., an 8-billion parameter model) that can punch far above their weight class by simply giving them more time to “think.”
- Hallucination Eradication: The integration of Process Reward Models acts as a real-time bullshit-detector, killing logically flawed branches before they are shown to the user.
- Dynamic Resource Allocation: You only pay for what you need. The model answers “What is the capital of France?” instantly, but spends 2 minutes of compute when asked to “Refactor this 5,000-line codebase.”
Latency and Inference Compute Limitations
- Extreme Latency: Test-time compute models are incredibly slow. Waiting 30 to 60 seconds for an answer makes them completely unusable for real-time voice assistants or fast-paced customer service chatbots.
- Inference CapEx Inflation: Generating and throwing away thousands of hidden “thinking tokens” makes the API cost per query exponentially higher than standard autoregressive models.
- Reward Model Hacking: If the PRM is flawed, the MCTS algorithm will eventually find a way to “game” the system, generating reasoning paths that score highly on the PRM but are actually nonsensical to humans.
Takeaway: You do not use a Test-Time Compute model to write an email or summarize a PDF. You use it when you need a mathematical proof, a secure software architecture, or a verified legal strategy, and you are willing to wait a minute to get it right.
Common Misconceptions
Misconception: The AI is searching the internet while it pauses.
Reality: The “thinking” phase is entirely internal. It is not Googling the answer; it is mathematically generating alternative solutions, debating itself, and grading its own logic using its internal reward models.
Misconception: It just runs the same prompt multiple times and picks the best one.
Reality: That is “Best-of-N” sampling, an older, less efficient technique. MCTS actually maps out a tree, mixing and matching successful sub-steps (e.g., taking the first half of Branch A and combining it with the second half of Branch C) to synthesize a perfect answer.
Misconception: This replaces pre-training scaling.
Reality: It is an orthogonal axis of scaling. To have an AI that thinks well during test-time, it still needs to be pre-trained on high-quality data to understand the foundational rules of the universe. The two scaling laws multiply each other.
What Most People Miss
The disruptive capability of Synthetic Data Generation.
The hidden superpower of Test-Time Compute models isn’t just answering questions; it is generating training data. When an MCTS model successfully navigates a complex math problem, it leaves behind a perfect, step-by-step “reasoning trace” (the exact sequence of thoughts that led to the correct answer).
AI labs are capturing millions of these verified, high-quality reasoning traces and using them as synthetic training data to teach smaller, cheaper models how to think. The slow, expensive Test-Time models are essentially acting as automated schoolteachers, generating the textbooks required to build the next generation of hyper-efficient AI.
Comparison Table
| Metric | Standard LLM (Autoregressive) | Test-Time Compute (MCTS + PRM) |
| Cognitive Paradigm | System 1 (Instinctual) | System 2 (Deliberate / Logical) |
| Compute Allocation | Constant per token | Dynamic (Scales with complexity) |
| Error Handling | Cannot backtrack (Compounds errors) | Detects errors, prunes, and backtracks |
| Latency | Instantaneous (Milliseconds) | High (Seconds to Minutes) |
| Best Use Case | Summarization, Chat, Translation | Advanced Math, Software Architecture, STEM |
Future Outlook
Next 12–24 Months
The era of Open-Source PRMs. The secret sauce of models like OpenAI’s o1 is the proprietary Process Reward Model that grades the thoughts. Over the next two years, the open-source community (led by labs like DeepSeek and Meta) will successfully train and release open-weights PRMs. This will democratize System 2 thinking, allowing any developer to wrap an MCTS algorithm around an open-source model like LLaMA 3, achieving frontier-level reasoning on local, private servers.
Next 3–5 Years
The scaling of Agentic Tool-Use Verification. Currently, test-time compute is used primarily for internal math and logic. Soon, the MCTS tree will incorporate external tools. The AI will branch out, execute a python script, test a web API, read the error code, backtrack, rewrite the code, and try again—all within the invisible “thinking” phase. The final output to the user will be the successful execution of a complex, multi-system workflow.
Next 10 Years
The Continuous Autonomous Researcher. By the mid-2030s, test-time compute will scale from minutes to weeks. An AI will be given a prompt like “Discover a more efficient solid-state battery material.” The model will run a continuous MCTS loop for weeks, orchestrating automated wet-labs, simulating molecular structures, grading the physical outcomes via advanced PRMs, and adjusting its hypotheses. Inference compute will scale to the point where AI conducts multi-year, Nobel-level research autonomously.
Most Likely Scenario
The autoregressive “instant guess” architecture hit a hard ceiling on complex logic. By treating language generation as a search problem—and utilizing PRMs to mathematically verify intermediate steps—Test-Time Compute has unlocked a new dimension of machine intelligence. While the latency and inference costs are currently high, the ability to guarantee logical accuracy without spending billions on pre-training fundamentally alters the economics of artificial intelligence, ushering in the era of true, deliberate machine reasoning.
Key Takeaways
- Standard AI models generate answers instantly, word-by-word. If they make a logical error early on, they cannot backtrack, leading to compounded hallucinations in math and code.
- Test-Time Compute Scaling allows the AI to “pause and think” during generation, trading higher inference compute costs for vastly superior logical accuracy.
- The system uses Monte Carlo Tree Search (MCTS) to generate multiple possible reasoning branches, and Process Reward Models (PRMs) to mathematically grade every single step.
- If a branch receives a bad grade from the PRM, the AI abandons it, backtracks, and tries a new logical path, effectively self-correcting before showing the answer to the user.
- This architecture shifts the AI industry’s economic bottleneck from the Training phase (building massive models) to the Inference phase (running intensive search algorithms).
Glossary
Autoregressive Generation: The standard method by which LLMs produce text, predicting the most statistically likely next single token based on the sequence that came before it.
Chain of Thought (CoT): A prompting or training technique where an AI explicitly writes out its intermediate reasoning steps before providing the final answer.
Monte Carlo Tree Search (MCTS): A heuristic search algorithm used in decision processes (famous for beating humans in Go) that explores multiple future pathways and focuses compute on the most promising branches.
Outcome Reward Model (ORM): An evaluator that only looks at the final output of an AI to determine if it is correct (Pass/Fail).
Process Reward Model (PRM): An advanced evaluator trained to grade the logical soundness of individual, intermediate steps in a reasoning process, enabling real-time error correction.
Test-Time Compute: The processing power expended by an AI model during the actual generation of an answer (inference), as opposed to compute spent during initial training.
Sources
OpenAI Research: Learning to Reason with LLMs (The o1 Architecture)
DeepMind / arXiv: Scaling LLM Test-Time Compute Optimally can be More Effective than Scaling Model Parameters
Hugging Face Research: Process Reward Models vs Outcome Reward Models in Mathematical Reasoning
SemiAnalysis: Inference Compute: The Next Frontier of AI Economics
Stanford AI Lab: Tree of Thoughts: Deliberate Problem Solving with Large Language Models